Category Archives: algorithms

A process or set of rules to be followed in calculations or other problem-solving operations, esp. by a computer.

Computer Algorithms: Lossy Image Compression with Run-Length Encoding

Introduction

Run-length encoding is a data compression algorithm that helps us encode large runs of repeating items by only sending one item from the run and a counter showing how many times this item is repeated. Unfortunately this technique is useless when trying to compress natural language texts, because they don’t have long runs of repeating elements. In the other hand RLE is useful when it comes to image compression, because images happen to have long runs pixels with identical color.

As you can see on the following picture we can compress consecutive pixels by only replacing each run with one pixel from it and a counter showing how many items it contains.

Lossless RLE for Images
Although lossless RLE can be quite effective for image compression, it is still not the best approach!

In this case we can save only counters for pixels that are repeated more than once. Such the input stream “aaaabbaba” will be compressed as “[4]a[2]baba”.

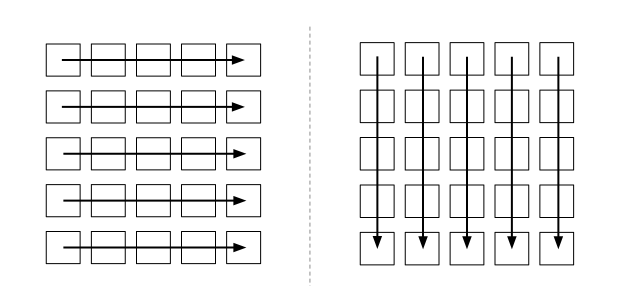
Actually there are several ways run-length encoding can be used for image compression. A possible way of compressing a picture can be either row by row or column by column, as it is shown on the picture below.
Row by row or column by column compression
Row by row or column by column compression.
Continue reading Computer Algorithms: Lossy Image Compression with Run-Length Encoding

Computer Algorithms: How to Determine the Day of the Week

Introduction

Do you know what day of the week was the day you were born? Monday or maybe Saturday? Well, perhaps you know that. Everybody know the day he’s born on, but do you know what day was the 31st January 1883? No? Well, there must be some method to determine any day in any century.

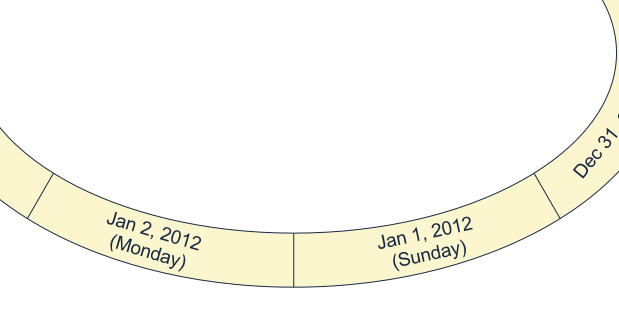
We know that 2012 started at Sunday. After we know that it’s easy to determine what day is the 2nd of January. It should be Monday. But things get a little more complex if we try to guess some date distant from January the 1st. Indeed 1st of Jan was on Sunday, but what day is 9th of May the same year. This is far more difficult to say. Of course we can go with a brute force approach and count from 1/Jan till 9/May, but that is quite slow and error prone.

Following Days
If 1st of January is Sunday the most logical thing to happen is 2nd of January to be Monday

So what we’ll do if we have to code a program that answers this question. The most easier way is to use a library. Almost every major library has built-in functions that can answer what day is on a given date. Such are date() in PHP or getDate() in JavaScript. But the question remains. How these library functions know the answer and how can we code such library function if our library doesn’t support such functionality?

There must be some algorithm to help us. Continue reading Computer Algorithms: How to Determine the Day of the Week

Computer Algorithms: Boyer-Moore String Searching

Introduction

Have you ever asked yourself which is the algorithm used to find a word after clicking Ctrl+F and typing something? Well I guess you know the answer from the title, but in this article you’ll find out how exactly this is done.

As we saw from the Morris-Pratt string searching we don’t need to compare the text and the pattern character by character. Some comparisons can be skipped in order to improve the performance of the string searching. Indeed the brute force string searching and the Rabin-Karp algorithm are quite slow only because they compare the pattern and the text character by character.

In the other hand the Morris-Pratt algorithm is a very good improvement of the brute force string searching, but the question remains. Is there any algorithm that is faster than Morris-Pratt – is there any way to skip more comparisons and to move the pattern faster.

It’s clear that if we have to find whether a single character is contained into a text we need at least “n” steps, where n is the length of the text. Once we have to find whether a pattern with the length of “m” is contained into a text with length of “n” the case is getting a little more complex.

However the answer is that there is such algorithm that is faster and more suitable than Morris-Pratt. This is the Boyer-Moore string searching.

Overview

Boyer-Moore is an algorithm that improves the performance of pattern searching into a text by considering some observations. It is defined in 1977 by Robert S. Boyer and J Strother Moore and it consist of some specific features.

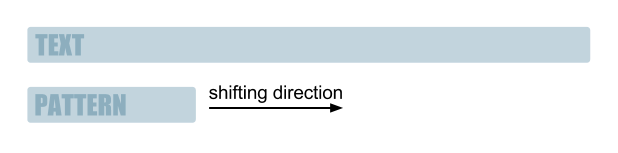
First of all this algorithm starts comparing the pattern from the leftmost part of text and moves it to the right, as on the picture below.

Boyer-Moore Shifting Direction
In Boyer-Moore the pattern is shifted from left to right!
Continue reading Computer Algorithms: Boyer-Moore String Searching

Computer Algorithms: Morris-Pratt String Searching

Introduction

We saw that neither brute force string searching nor Rabin-Karp string searching are effective. However in order to improve some algorithm, first we need to understand its principles in detail. We know already that brute force string matching is slow and we tried to improve it somehow by using a hash function in the Rabin-Karp algorithm. The problem is that Rabin-Karp has the same complexity as brute force string matching, which is O(mn).

Obviously we need a different approach, but to come with a different approach let’s see what’s wrong with brute force string searching. Indeed by taking a closer look at its principles we can answer the question.

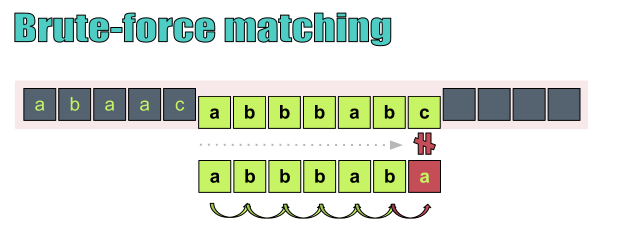
In brute force matching we checked each character of the text with the first character of the pattern. In case of a match we shifted the comparison between the second character of the pattern and the next character of the text. The problem is that in case of a mismatch we must go several positions back in the text. Well in fact this technique can’t be optimized.

Morris-Pratt brute force string matching
In brute force string matching in case of a mismatch we go back and we compare characters that has been compared already!
Continue reading Computer Algorithms: Morris-Pratt String Searching

Computer Algorithms: Rabin-Karp String Searching

Introduction

Brute force string matching is the a very basic sub-string matching algorithm, but it’s good for some reasons. For example it doesn’t require preprocessing of the text or the pattern. The problem is that it’s very slow. That is why in many cases brute force matching can’t be very useful. For pattern matching we need something faster, but to understand other sub-string matching algorithms let’s take a look once again on brute force matching.

In brute force sub-string matching we checked every single character from the text with the first character of the pattern. Once we have a match between them we shift the comparison between the second character of the pattern with the next character of the text, as shown on the picture below.

Brute Froce Principles
Brute force string matching is slow because it compares every single character from the pattern and the text!
Continue reading Computer Algorithms: Rabin-Karp String Searching